

lousho-studio — the SDK (lousho)
does not contain it. One Studio server shows every agent you have: the spec-v2
graph agents saved in your project folders, code agents Studio finds by scanning
a workspace, and agents running anywhere that report to the observe collector.
This page covers installing and starting Studio, workspaces, which SDK runs a
workspace’s agents (and what each banner means), the collector, and how agents
deployed on other machines show up here. Using Studio covers
the builder, the playground, traces and the rest of the app; the builder,
Author and lifecycle screens have their own pages: the visual
builder, the Agent
Author and versions, triggers and
publishing.
Install and start
Any of these works:lousho installed, the SDK’s
launcher finds the installed Studio and opens this folder as a workspace:
lousho studio accepts --port and --host and passes them through; run
lousho studio --help for its options. --prod and --dev only apply inside
the SDK’s own repository checkout (see Dev mode).
lousho-studio (and npx lousho-studio) take the same flags:
The server prints its URL,
http://127.0.0.1:4750/?token=<random>. The
?token= is a per-launch access token: the page keeps it for that tab and
sends it on every API call, so open the printed URL, not the bare host (see
Access token).
Opening Studio lands on the Agents list (#/agents): your saved agents as
cards, plus a New agent menu. Opening or creating one takes you to its
Canvas tab — the builder: the build toolbar (the agent’s name and run
status, the model badge, then Debug, Stop, Run, Import, Export and Save),
the agent rail (your saved agents plus a node/hook palette), the canvas, the
Inspector (right), and a bottom drawer with Test, Problems, Logs, Trace,
Output, History and Settings tabs. An agent opens with nothing selected and
the whole graph fitted in view; the Inspector stays folded away until you
select a node, or press the Inspector button at the canvas’s top-right
(its accessible name is “Show inspector”), which is remembered. The other
screens are one click away in the navigation; see Navigation.
Below 860px wide the navigation becomes a drawer opened from the
Navigation (menu) button at the top; picking a screen, the scrim or Esc
closes it. On the builder the agent rail and the Inspector become
slide-over panels you open from the top bar; Run (or Stop) and Save stay in
the bar, and Debug, Import, Export and the model badge move into its More
actions (⋯) menu.
Workspaces
A workspace is a project folder on disk. The folder you launch Studio from is added automatically; add more with Add workspace → folder path (or the Add workspace… entry in the switcher). The switcher at the top of the nav lists All workspaces, each workspace, and Add workspace….#/agents is the all-workspaces list; an agent route
is #/w/<workspace>/agents/<id>/<tab>.
Things live in three places:
On first launch after the split, if a workspace still has a project-level
.lousho/settings.json or .lousho/secrets.json, Studio offers Import
settings and keys from <workspace> once, copies them into
~/.lousho/studio/, and leaves the originals alone.
Three kinds of agent
The all-workspaces agent list mixes three kinds:
Observed agents whose collector
project matches a workspace id appear under
that workspace (see See agents running elsewhere).
The rest are grouped under Elsewhere.
Which SDK runs your agents
For each workspace Studio picks how agent processes run:- Bridge — the normal case. Studio spawns
lousho bridgefrom the SDK installed in that project (lousho), so runs use the project’s own SDK version. This matters because a project’s{ file }tools and skills import that project’s dependencies, which only resolve inside the project. - In-process — Studio’s own built-in SDK, used when the project has no SDK installed or its checkout is not built.
- Read-only — the project’s SDK is too old or speaks a protocol this Studio does not know, so edits are refused until it is fixed.
While a workspace is read-only, writes under its agents (saves, drafts, runs,
deploys) are refused; reads still work.
A few features still need Studio’s built-in SDK and are unavailable on
bridge workspaces:
- Flow runs:
Flow runs need Studio's built-in SDK for now. Remove the project's SDK from this workspace or run the flow from code. - Breakpoints:
Breakpoints need Studio's built-in SDK for now. - Time travel:
Time travel is not available yet for projects that run their own SDK.
The collector
Everything under Observe, Evaluate and Assets — and run reporting — reads the observe collector. On boot Studio probes the configured URL (defaulthttp://127.0.0.1:7777):
- Attached — a
lousho observedaemon is already running there; Studio uses it. - Started — none answered on loopback, so Studio started its own and stops it on exit. It never stops a daemon it did not start.
- Remote — a non-loopback URL (team or hosted collector); Studio probes it but does not start or stop anything there.
- Down — nothing answers; daemon screens show the start command instead of data and recover on their own.
Attached to <url>, Started by Studio on <url>, Remote collector at <url>, Not reachable: <error>). Settings → Collector sets a remote URL and bearer
token; create a token with lousho observe token create --project <name>.
LOUSHO_OBSERVE_URL and LOUSHO_OBSERVE_TOKEN in Studio’s own environment
override the stored setting, and LOUSHO_STUDIO_COLLECTOR=0 stops Studio
from auto-starting a local daemon.
See agents running elsewhere
An agent deployed on another machine — a server, CI, a teammate’s laptop — shows up in Studio once it reports to a collector Studio can read. Reporting is pure SDK configuration; nothing in the agent is Studio-specific:
Point Studio at the same collector under Settings → Collector (or with
LOUSHO_OBSERVE_URL/LOUSHO_OBSERVE_TOKEN in Studio’s environment), and the
deployed agent’s traces, scores and sessions appear in Studio’s Observe
screens.
Updating
Studio (lousho-studio) and the SDK (lousho) are separate
packages and update independently:
MIN_BRIDGE_SDK_VERSION — the SDK version this Studio was built against. Older
SDKs get the read-only banner above; newer ones get the “update Studio” banner.
Bridge workspaces also need lousho bridge in the project’s SDK, which speaks
bridge protocol 1.
Using Studio
Access token
The studio can store provider keys, start runs and execute hook code, so its API is locked to the browser tab you opened from the printed URL:- Each launch mints a random token and prints it in the URL (
?token=...). The page keeps it for that tab (it survives a reload) and sends it on every API call (x-lousho-studio-tokenheader) and on the WebSocket (?token=query). A request without it gets401. Opening the barehttp://127.0.0.1:4750in a new tab loads the page, but its API calls fail until you use the printed URL. - The server sends no CORS headers and refuses (
403) a request whoseOriginis not the studio’s own, or whoseHostis not a loopback name (localhost,127.0.0.1,[::1]) or the--hostyou bound to. With--host 0.0.0.0anyHostis accepted and the token is the only gate. GET /healthand the static client need no token.
curl, pass the token: curl -H "x-lousho-studio-token: $TOKEN" localhost:4750/agents.
lousho studio hands these to the processes it starts through environment
variables; you only set them yourself when you start the studio server
without the CLI:
Where agents live
Each workspace’s agent specs and run state live under.lousho/ in that
project folder (agent YAML files under .lousho/agents/, checkpoints and
approvals alongside them) - the same .lousho/ layout lousho dev/lousho build use, so the files travel with the project and stay diffable.
Studio-wide state (settings, secrets, the workspace registry) lives in
~/.lousho/studio/ instead; see Workspaces. Those YAML files
are Agent spec v2 documents, which that page explains
field by field.
The Agents screen’s agent rail lists exactly the agents in that workspace’s
.lousho/agents/: a YAML file you add there shows up, and an agent you
create in the studio is written there at once (autosave and Save both
write the file), so it can be chatted with straight away. Another workspace
shows only its own agents. The browser keeps nothing but a draft of an edit
that could not reach the server (it is pushed on the next load), stored per
workspace directory. A file in .lousho/agents/ that no longer parses is
skipped with a warning in the server log.
Production vs. dev mode
An installed Studio (lousho-studio, npx lousho-studio, or
lousho studio finding it) is always production mode: a single Express
server serves both the REST/WebSocket API and the pre-built client (React
app) as static files, on one port. There is no separate Vite dev server and
no TypeScript loader involved.
Dev mode - the API server running from TypeScript via tsx next to a Vite
dev server with hot-module reload - exists only inside the SDK’s own
repository checkout, for people contributing to Studio itself. There
lousho studio --dev (or --prod to force the built bundle) picks the mode;
run without either flag it auto-detects based on whether
apps/agent-forge/dist-server exists. See Dev mode.
Navigation
The left navigation lists every screen, grouped:
Off the builder a page header names the screen and keeps the live run
status pill at the end of its title row, after any chips the screen adds (a
prompt’s labels, say). Under Settings, a small card shows the collector status (see
The collector). The button beside the
Agent Forge name at the top of the nav (Collapse navigation)
shrinks it to a rail of icons; hover an icon for its name. The choice is
remembered across reloads. Below 860px wide the nav is always the full
drawer.
Routes and deep links
Every screen has a hash route, and a screen’s filters live in the URL’s query string, so a reload, a bookmark or a pasted link opens the same screen with the same filters. Defaults are never written (a bare#/traces is the
default 24 h list). Filter, sort and page edits replace the current history
entry, and opening a row pushes one, so the browser’s Back returns from a
trace to the list instead of walking through filter edits. An empty or
unknown hash goes to #/agents (the ?token= stays).
A time range picked from a preset other than the default is written as
absolute
from/to bounds, so a reload shows exactly the same rows. The
full route list is apps/agent-forge/src/screens/routeTable.ts.
Keyboard
The command palette lists Go to every nav screen, Open agent
for each saved agent, and Toggle theme (light/dark, remembered in the
browser); type to filter. Paste a trace id (8 or more hex digits and
dashes) and the first entry is Open trace for it. Arrow keys move,
Enter runs.
The builder’s own shortcuts — save version, undo/redo, palette search,
node delete — are listed in the visual builder.
S skips
the item (see Annotation queues).
Status words
Every status in the Studio is the same pill:- Runs:
ok,error,running,interrupted(the agent’s process died mid-run; see The observe daemon). - Agents:
healthy,stale(missed heartbeats),down,stopped. - Threads:
active,ended(idle, see Idle sessions),interrupted. - Scores:
pass,fail. - Builder runs:
idle,running,done,stopped,error,awaiting approval.
The collector (observe daemon)
Everything under Observe, Evaluate and Assets reads the observe collector through the Studio server’s/observe proxy, which calls whatever URL the
collector manager resolved (see The collector). The proxy
forwards reads plus the writes the screens make (feedback scores, new prompt
versions from the Playground, prompt label moves, hub entry edits, dataset
and example writes, annotation queue writes, evaluator rule writes); every
other write, ingest above all, is refused with 405. When a bearer token is
configured the proxy sends it to the collector on every read and write (as
run reporting and the judge evaluators do), so the screens also work against
a collector started with --require-token. Without it, such a collector
answers 401 to every /api/ read and the screens show that error instead
of data (/health still answers, so the collector card says running). The
browser’s own credentials (the Studio token, cookies, Authorization) are
never passed on.
The collector card at the bottom of the nav shows the resolved mode —
Attached to <url>, Started by Studio on <url>, Remote collector
at <url> or Not reachable: <error> — and keeps polling. While the
collector is down, each daemon screen shows the command to start it instead
of an error, keeps its URL, and swaps the data back in by itself once it
answers. The Agents screen and Playground runs do not need the collector.
Screens
Agents
#/agents is the agents list: a card per agent in .lousho/agents/, a
New agent menu (Blank agent, From template,
Describe with AI — see the Agent Author — or
Import from file…), and search and label filters.
Opening a card goes to its Canvas tab, the builder — see
the visual builder and the
first-agent walkthrough. #/agents/<id> (the
legacy builder URL) redirects to #/agents/<id>/canvas. Leaving the
builder with unsaved changes asks first. Runs started there report to the
observe daemon, and the Run status pill’s Open trace link opens the
run on the Trace screen.
Playground
#/playground (Build > Playground) tries messages against a model
without editing an agent:
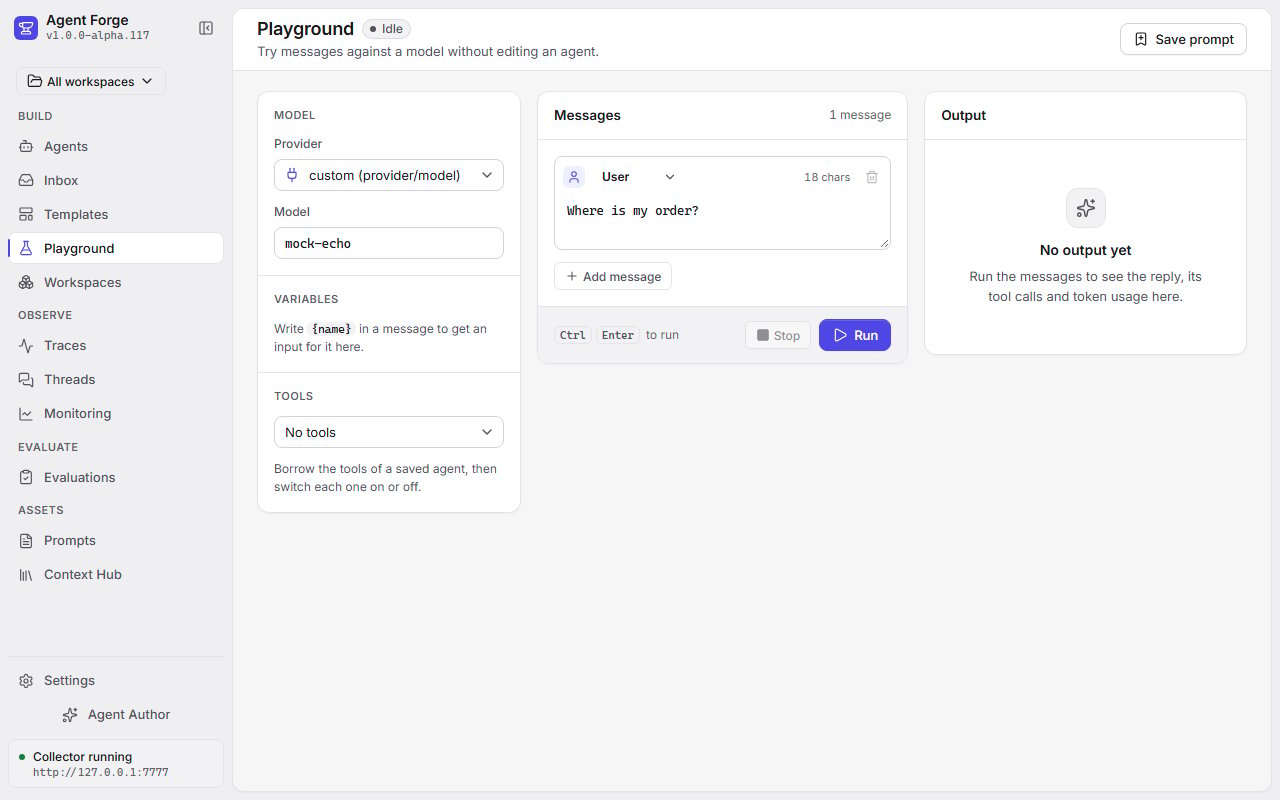
- Messages: system, user and assistant message cards. Every
{name}placeholder in any message gets a Variables input in the left settings card, in the order the names first appear. - Model: a provider (the ones with a key under Settings > Provider keys,
plus
ollamaandmock;mockwhen nothing is configured) and a model name, sent asprovider/model. - Tools: pick a saved agent to borrow its tools, then switch each one on or off.
- Run (or Ctrl/Cmd+Enter in the messages) streams the reply as it arrives; Stop aborts it. Tool calls show as cards that open to their arguments. When the run finishes, the output shows its tokens in and out, latency and cost (when the model’s price is known), and Open trace goes to its trace.
- Save prompt (in the page header) opens a card whose Save as new prompt version pushes the system message (and its variables) to the prompt registry, under the loaded prompt’s name or one you type. It is disabled while there is no system message.
#/playground?trace=<traceId>&fromObs=<obsId>, which loads
that generation’s messages and model. #/playground?prompt=<name>[@<label or version>] (the Prompts screen’s Open in Playground) loads a registry
prompt (latest by default) as the system message and records it on the
run’s trace. Both read the observe daemon: when it is down, the Playground
says so and keeps an empty editor, and runs still work. Runs go through the
playground run endpoint and report as agent
playground.
Workspaces
#/workspaces lists the workspaces the typed workspaces API knows: name and
domain, page count, a Valid/Invalid (n) badge from the workspace’s
problems, the live revision and a last-run column (filled in by a later
ticket). #/workspaces/<id> opens one workspace with a header that carries
the live revision, the problems badge, an Draft open badge while a draft
exists, and disabled Run/Chat actions; a left nav switches between
the overview, main-agent, pages, agents, runs, improve and
revisions sections, the ones not built yet naming their ticket. Every edit
is a typed authoring operation sent through ApiClient.call('applyOps', …)
into a draft with expectedRevision; the draft is applied or discarded
later. When the live revision moved under an open screen the operation gets a
409, the latest revision reloads and a toast says “This workspace changed
since you opened it.” The screens call only the workspaces API
(/api/workspaces, mounted by a later ticket), through an injected
ApiClient, so they run on fixtures today and move to the Next.js app later.
Traces
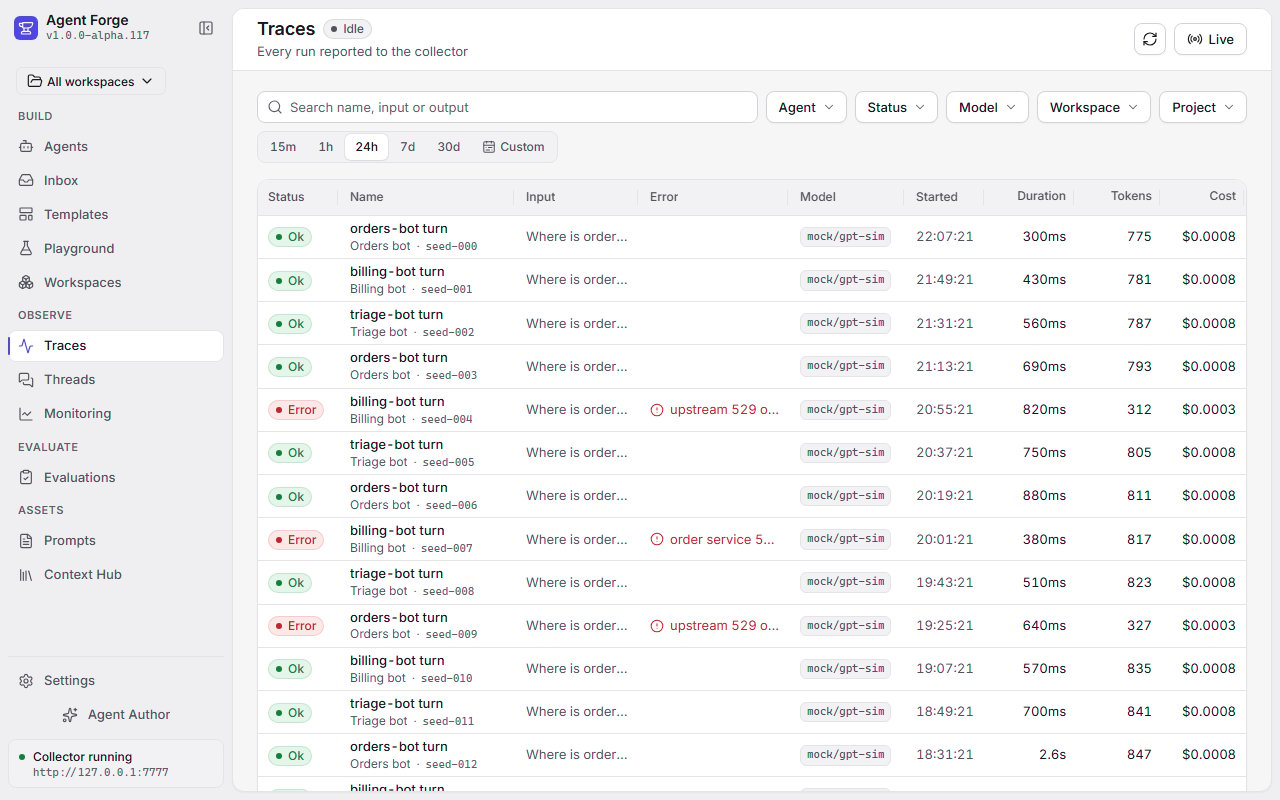
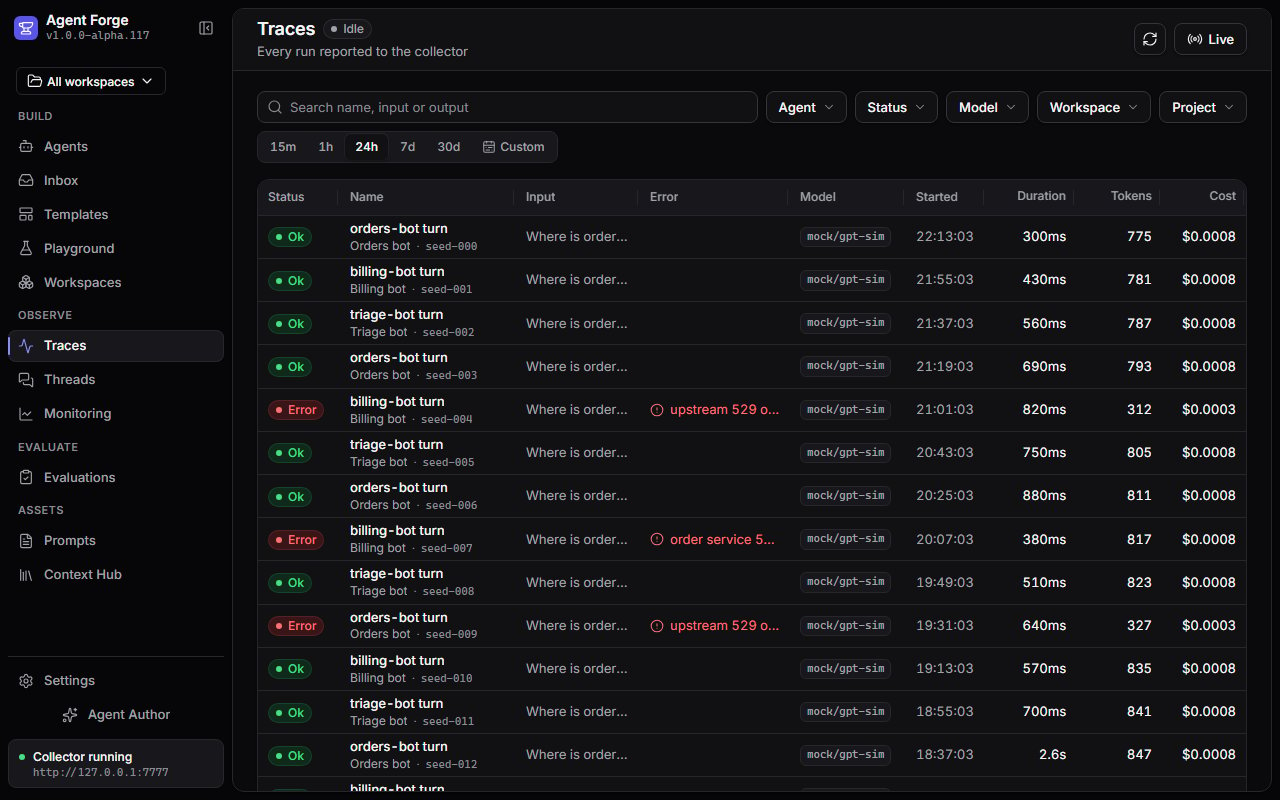
#/traces lists the daemon’s runs, newest first: status, name, agent,
input and output previews, error message, model, start, duration, tokens
and cost (narrow windows hide the less important columns). Filter with the
search box (name, input or output), the Agent, Status, Model and
Project facets, and a time range (15m, 1h, 24h, 7d, 30d or Custom;
default the last 24 h). Click Duration, Tokens or Cost to sort
by it. 50 rows a page. The page header’s refresh icon (Refresh) re-fetches the list
now, and Live (a toggle) refreshes it every 5 seconds until you switch
it off or the daemon goes down. A prompt filter (set by the Prompts screen’s
“Runs using this version” link) shows as a removable chip.
Trace
#/traces/<trace id> is one run. The header has its name, status, agent
(a link to the agent’s traces), model, start, duration, tokens, cost and
session (a link to its thread), plus Copy link, Add to dataset,
Add to queue and, when the run has a model call, Open in Playground.
All traces in the page header goes back to the list.
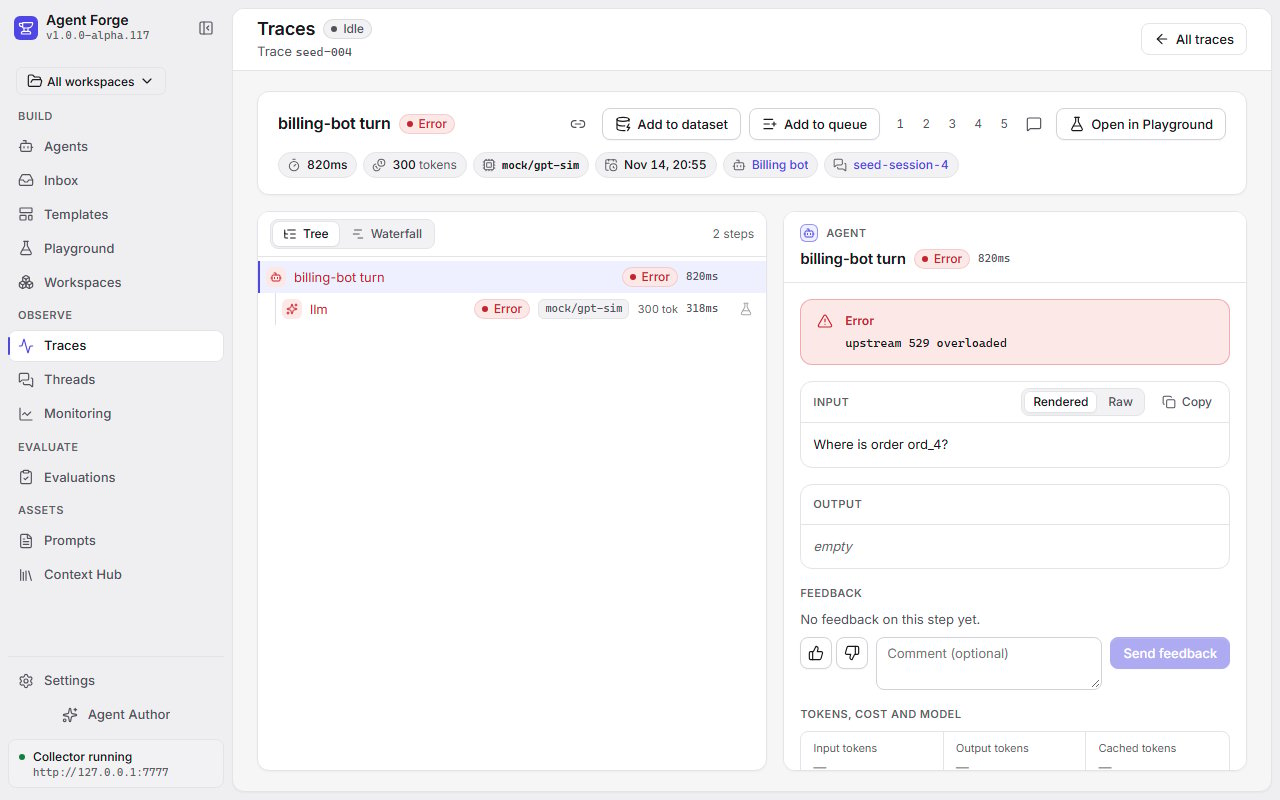
?obs= in the URL. The inspector shows, in order:
- Error: the failure message, when the step failed.
- Input and Output: messages render as chat bubbles with tool calls as chips; switch between Rendered, Raw and JSON (for JSON content), and copy either block.
- Feedback: the step’s scores, and thumbs up / down with an optional
comment, saved as a
feedbackscore (1or0, sourcehuman). On the root step it scores the whole trace. - Tokens, cost and model.
- Attributes: the step’s raw attributes as a JSON tree.
Threads
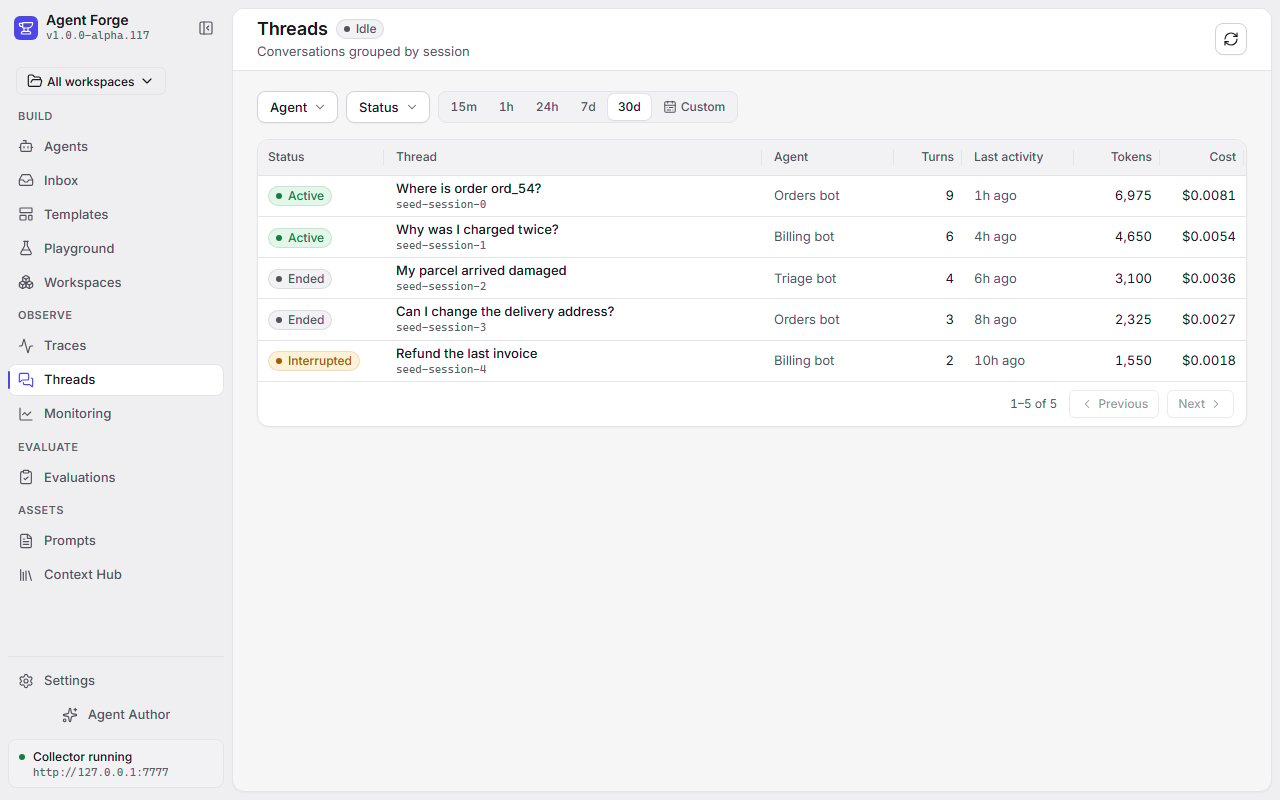
#/threads lists sessions: status, session id, agent, last input, turns,
start, duration, tokens and cost, filtered by agent, status and time range
(default 30 days). A session appears once agent runs carry a sessionId.
#/threads/<session id> shows the conversation: every turn (run) oldest
first, with its input and output (or error) and an Open trace link.
Monitoring
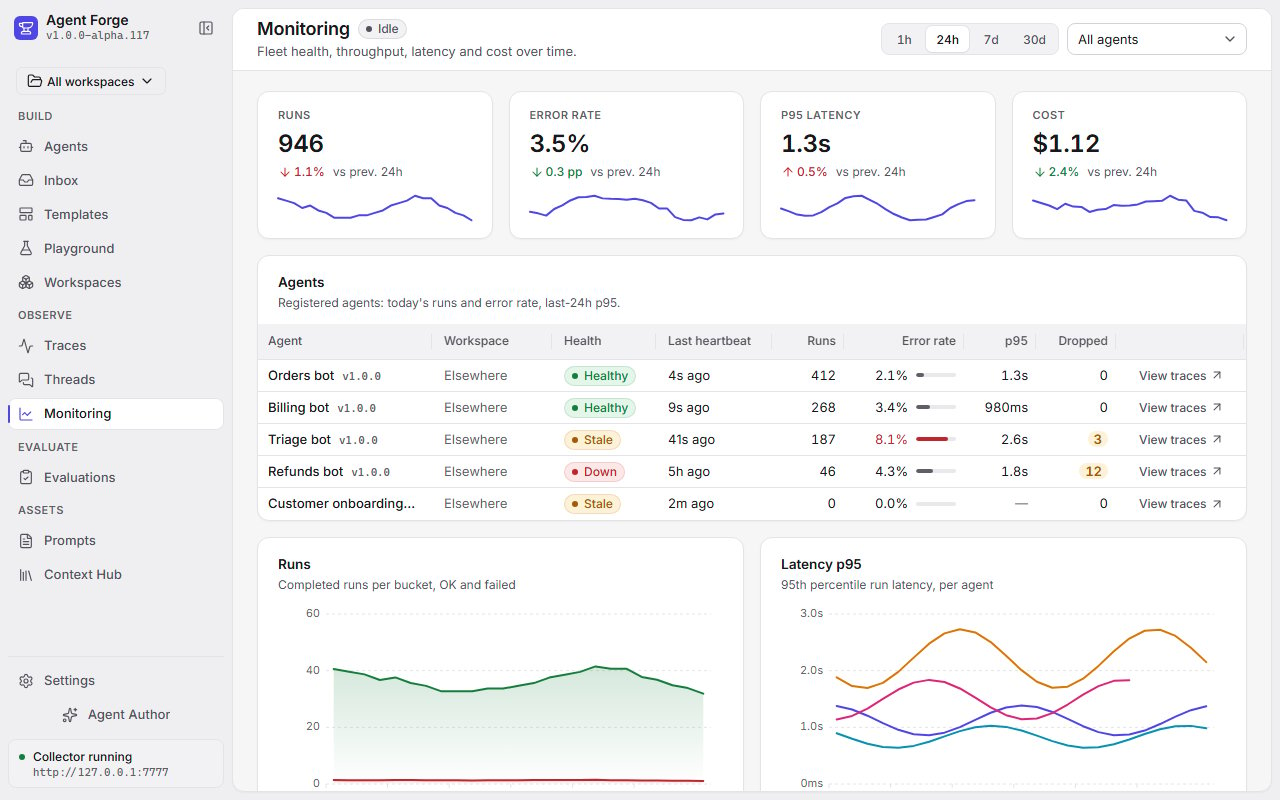
#/monitoring is the “is my fleet up” screen and refreshes itself every
15 seconds. The fleet table lists every agent that has reported: status,
last heartbeat, runs today, error rate, p95 latency over 24 h, the
reporter’s dropped-event count and a link to its traces. Below it, pick a
window (1h, 24h, 7d, 30d) and an agent, and read five charts: Runs,
Latency p95 and Error rate (per agent), Cost and Tokens.
Click a chart’s bucket to open Traces filtered to that bucket’s time (and
agent).
Evaluations
Evaluations in the nav opens#/evals/scores. A sub-navigation at the
top of every Evaluations screen (Scores, Datasets, Evaluators,
Annotation queues) moves between them.
Scores
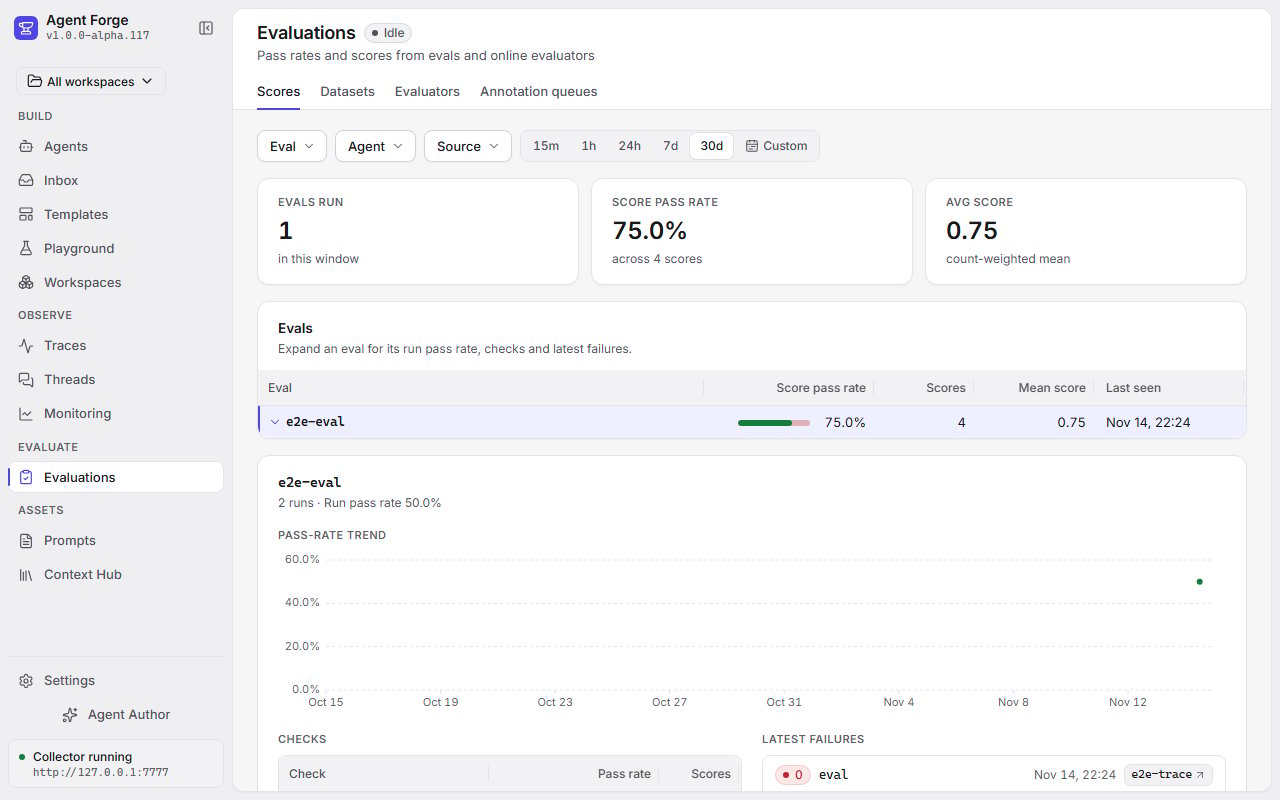
eval, judge, human,
online) and time range (default 30 days). Click an eval to expand it: the
run count and run pass rate, a pass-rate trend, the pass rate of each check
(worst first) and the latest failures, each linking to its trace (and step).
A score counts as a pass when its value is exactly 1. eval and judge
scores (an eval’s assertions and its llmJudge / t.judge() checks, which
write a comment only when they fail) also pass when they have no failure
comment. human and online scores are decided by value alone, so a 0 (a
thumbs-down, a rule that returned 0), a 0.9 or an empty value is a failure.
The table and the expanded detail use the same rule.
Where eval scores come from: Evals.
Datasets
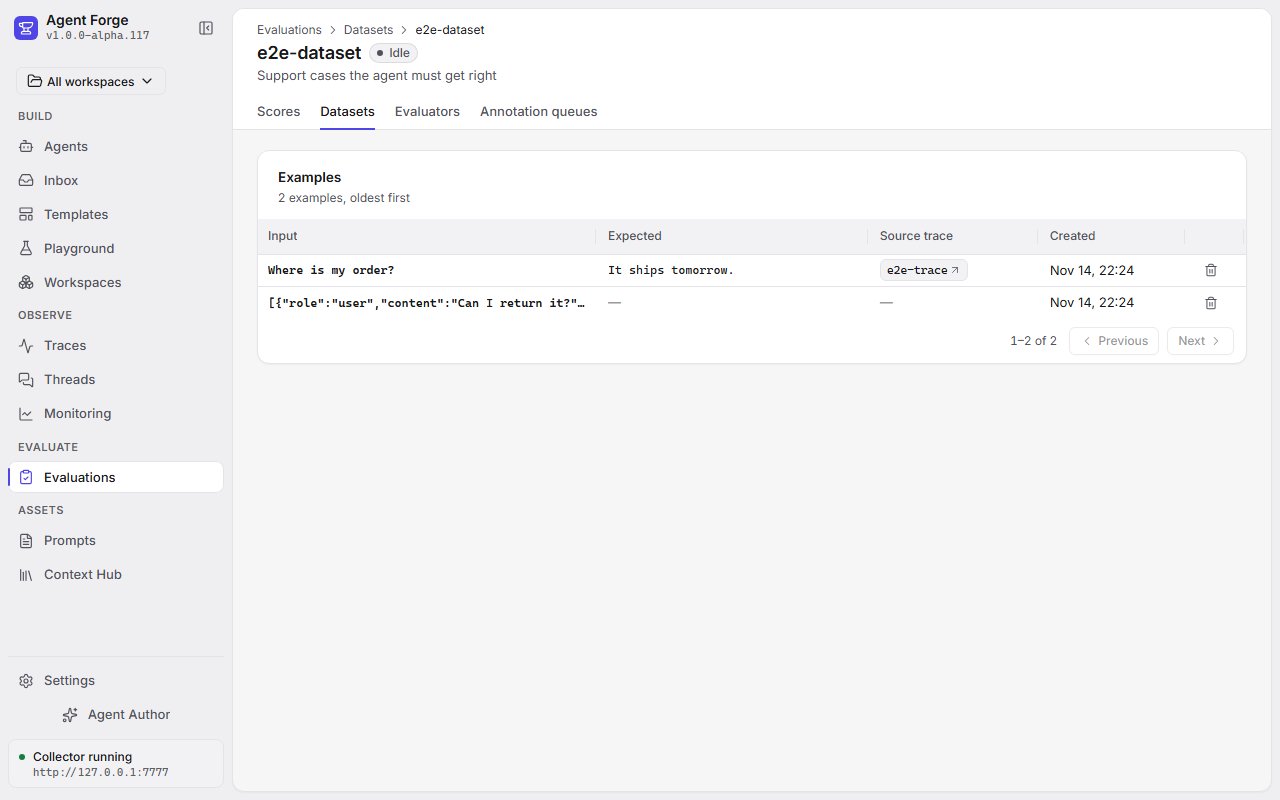
#/evals/datasets lists the datasets with their example counts, and has a
New dataset form (a name and an optional description). Open one to see
its examples (input, expected value, source trace); open an example to see
it in full, or Delete it (asks first). Examples come from a trace’s
Add to dataset, or by hand through the
datasets API. An eval runs over a dataset
with defineEval({ dataset: 'name' }) (see
Datasets).
Evaluators
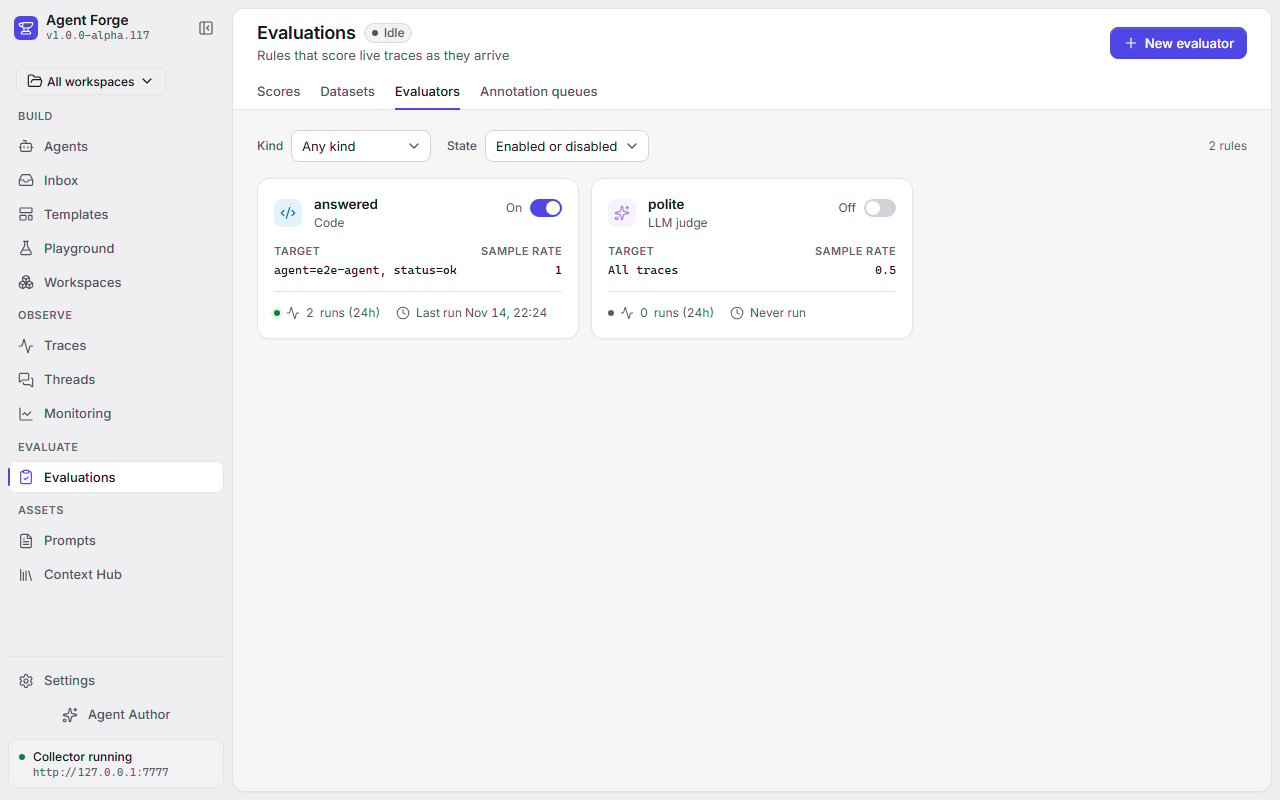
#/evals/evaluators manages online evaluator
rules: rules that score new
traces as they finish. Their scores carry the rule’s name and show on Scores
with source online.
The list shows each rule’s name, kind (code or judge), filter (or “All
traces”), sample rate, an Enabled switch (flips the rule on or off at
once), and its Last run and Runs (24h), counted from the newest 1000
online scores (a + after the count means that read was full, so the count
is a floor). Filter by Kind and State (?kind=, ?enabled=), 50
rules a page.
New evaluator opens the form; open a rule (#/evals/evaluators/<rule id>) to edit it in the same form, where Save changes sends only the
fields you changed and Delete removes the rule after a confirm (its past
scores stay). The form has a name, a sample rate (0-1), an enabled box, the
filter (agent, status ok or error, name contains), and the kind:
- A code rule is a function
(trace) => number | { value, comment }, prefilled with a working sample. The observe daemon runs it in its isolate sandbox, so code rules run whether or not the Studio is open (see Online evaluators). - A judge rule is a provider, a model and a rubric. The daemon has no
provider keys, so the Studio runs judges, with a key stored in Settings or
the provider’s environment variable where the Studio runs (the stored key
wins); the provider list offers the providers that have either, plus
ollamaandmock. With no key at all the judge option is disabled, with a link to Settings. Judges run only while Studio is running; until then their jobs wait in the daemon (see Judge rules). SetLOUSHO_STUDIO_JUDGE=0on the Studio server to turn its judge loop off.
?trace=
prefills it) and shows the value and comment; no score is written. The
Studio runs a judge rule itself and forwards a code rule to the daemon. An
unknown trace shows “Trace not found”.
Annotation queues
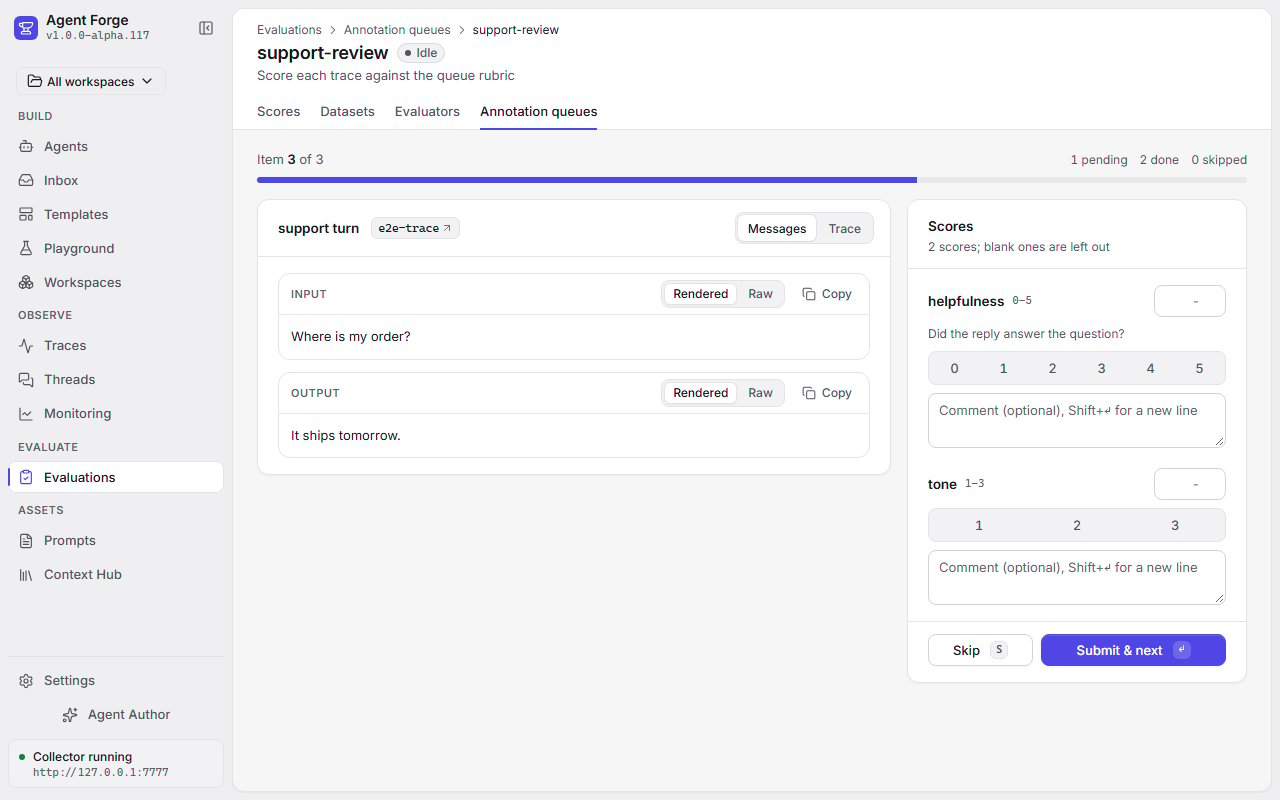
#/evals/queues lists the queues (pending, done, skipped) and has a New
annotation queue form: a name and a rubric, one row per score (name,
optional description, optional min and max). Add traces from a trace’s
Add to queue (or many at once with the
queue API). Open a queue to review
it: the next pending item’s trace in the trace viewer, beside one number
input (within the rubric’s bounds) and an optional comment per rubric
entry. Submit (Enter) saves the filled-in scores as human scores on the
trace and moves to the next item; Skip (S) skips it. A blank input is
not scored. When nothing is pending the screen says the queue is empty.
Prompts
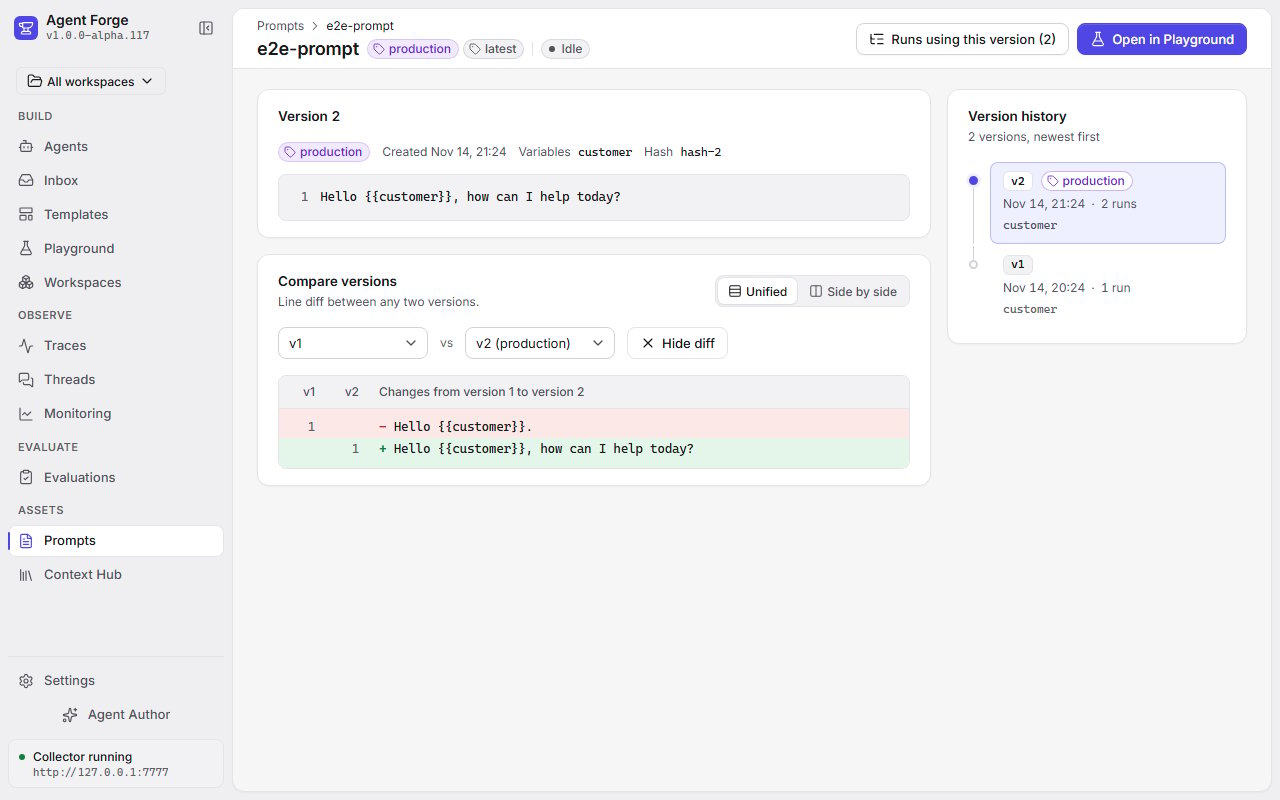
#/prompts lists the registry, one row per prompt: latest version, labels,
version count, runs that used it, and when it was updated; the search box
filters the list by name. Open one (#/prompts/<name>, or @<version> /
@<label> to select a version):
- The header: the prompt’s name with the selected version’s labels,
Runs using this version (Traces filtered by
prompt=<name>@<version>) and Open in Playground. - The selected version’s text, with line numbers, and Move
<label>here for each of the prompt’s labels that points elsewhere: a label points at exactly one version, so this moves it (the same aslousho prompt label, see CLI). - Compare versions: pick two versions for a diff (
?diff=a,b), shown Unified or Side by side. - The version history, a timeline beside the text; pick a version to
select it (
j/kmove between versions).
Context Hub
#/hub shows the context hub’s
namespaces. The daemon serves hub entries only on behalf of an agent, so
pick who you are Viewing as (default the first agent by name) and,
optionally, a scope (private or fleet). Open a namespace to see its
entries as cards (key, scope, a value preview, writer, last update and
TTL); open a card to see the full value (JSON as a tree) beside the list.
A fleet entry has an Edit button that republishes it (which restarts
its TTL).
Settings
#/settings is one column of cards: Appearance (theme Light, Dark or
System, and table density Compact or Comfortable, both remembered in this
browser; until you pick a density each table keeps its screen’s default),
Provider keys, Settings profile, Deploy target, Collector
(whether the observe daemon answers, its address, and lousho observe start
when it is down) and Keyboard shortcuts (the same list as the ? sheet).
The builder drawer’s Settings tab shows only the provider keys, profile
and deploy cards; see Settings, secrets and deploy wiring.
First-agent walkthrough
-
Create an agent. On the agents list (
#/agents) click New agent and pick Blank agent - it starts from an empty canvas, which is the fastest way to try things out without any API keys (From template offers ready-made starting points instead). Agent Forge creates the agent (.lousho/agents/<id>.yaml, withname:in the spec) and opens it on the canvas. The open agent’s card has Rename and Delete. Rename moves the spec to the new name; earlier chats, traces and checkpoints stay under the old one. -
Look at the graph. A blank agent is a single agent node. Drag more
nodes in from the rail’s Nodes tab (a Tool, an MCP server,
a Guardrail, a Chat trigger, an Output schema — the full
list is in the visual builder), or
click (or press
Enter on) a Nodes item to add it at the centre of the canvas, and
connect them by
dragging between their handles. Each node card shows its name, an agent
node’s
provider/modelchip, and the node’s status in the current run (idleuntil a run reaches it). Click a node to edit its settings in the Inspector on the right; its Problems, Settings and Debug sections collapse, and each stays the way you left it. -
Run it. Click Run in the top bar. With the
mockprovider there’s nothing to configure - it returns deterministic canned output, which is exactly the point for trying the rest of the UI without needing a real LLM API key. The status pill in the top bar tracks the run (running→done,stoppedafter you press Stop,errororawaiting approval), and once the run’s trace id is known an Open trace link next to it opens the run at#/traces/<traceId>(in the narrow layout it is in the More menu). Builder runs report to the observe collector as agent<agent id>, the same way the Playground does (see The collector): a collector that is down only drops events and never fails the run, and message content is sent only to a loopback collector (never to the trace files or the live Trace tab). Run sends a fixed prompt, which the Test tab’s chat shows as a Run input bubble instead of a message from you. If the studio server goes away, a banner says the connection was lost and the studio reconnects when it is back. -
Watch it in the debug console. Open the bottom drawer’s Logs
tab for a live, filterable log feed of the run (trigger/llm/tool/
sandbox/checkpoint/approval events), or Trace for the run’s steps in
the same trace viewer the Traces screen uses (a tree or a waterfall, with
an inspector for the selected step).
Turn on Debug in the top bar (or set a breakpoint on a node in the
Inspector) to pause the run at LLM/tool boundaries and step through it
with the debug bar’s Step/Continue controls; expand “Live
message array” there to inspect the in-flight message list. Output
shows the full
ExecutionResult(messages, tool calls, usage, steps) as a collapsible JSON tree once the run finishes or pauses. Drag the drawer’s top edge (or focus it and use the arrow keys) to resize it; the height is remembered. Trace history. Every run is also saved as a trace file, so the Trace tab keeps the runs of the agent after the page is reloaded or the server restarted. A list on the left shows the agent’s past runs, newest first (start time, duration, model calls, tokens in/out, cost, status), with a Live entry on top while a run is active; choose one to open its steps in the same viewer: each step’s kind (model call, tool call or span), model, tokens and duration, failed steps in the error colour with the failure message in the inspector, and steps still running ticking live. Selecting a step highlights its node on the canvas. The list refreshes when a run ends. The files are the oneslousho tracesreads, in.lousho/agents/<agent id>/traces/<day>/<trace id>.jsonlunder the workspace folder (see Local traces):npx lousho traces --dir .lousho/agents/<agent id>/tracesshows the same runs in the terminal, and deleting the agent’s folder deletes its traces. The tab shows what the spans hold: model and tool names, token counts, cost, durations and error messages, and in the inspector’s Input, Output and Attributes sections the attributes, which carry prompt and tool content. The server reads traces only from that folder (an id with a path separator is a 400) and never sends the file path to the browser. Keep.lousho/out of version control. -
Chat with it. The chat in the bottom drawer’s Test tab is a
separate conversational
transport (
POST /agents/:id/message, streamed back over the same WebSocket as everything else) - send it a message and it replies in the thread, independent of the graph “Run” button above. Each agent keeps its own chat history (+ New chatstarts a fresh session; old ones stay browsable). - Approve a paused tool call. Add a Tool node, open it in the Inspector, and pick a tool - some tools (or an agent’s own policy) can require human approval before running. When a run or chat hits one, an inline approval card appears (in the top bar for a graph run, or as a message bubble in the chat thread) showing the tool name and its arguments. Click Approve to let it proceed or Reject to abort that call; the run resumes automatically either way.
Hooks
Hooks are small, sandboxed functions that run immediately before or after a tool call or a model call - the same mechanism the SDK core exposes asHookRegistry/AgentHook (see
API Overview), authored visually as hooks[] entries
on the agent.
To add one:
- Drag a Hook entry from the rail’s Nodes tab (Safety group) onto
the canvas, or click it while the agent is open; it attaches to the
agent as a node. Each spec
hooksentry is one node. - Click the hook node and edit its fields in the Inspector: an id, a
name, the Source (Code here for an inline body, or File for
a
.ts/.jsfile inside the agent folder), the Runs point - Before/After each tool call or Before/After each model call - the on switch, and the code itself in a CodeMirror editor, with starter templates (redact-pii,rate-limit,audit-log,inject-context) filtered to the current point. - The code is the body of an async function invoked as
hook(ctx)inside a sandboxed subprocess (server/hookSandbox.ts) - never in the browser or the API server process itself:- For a tool-call point,
ctxis{ toolName, args, result?, error? }. A pre-hook can mutatectx.args; a post-hook can inspect/mutatectx.result/ctx.error. Returnctx. - For a model-call point,
ctxis{ messages, model }. Mutate/push ontoctx.messagesand returnctx. - Throwing aborts the step - a rate-limit hook, for example, throws to block the tool call outright rather than letting it run.
- For a tool-call point,
- Switch a hook off without removing it, or delete its node; only enabled hooks are compiled into the run.
redact-pii
starter template) -
hooks entries in the agent’s YAML;
the server compiles enabled hooks into a real HookRegistry for the run
(server/compileHooks.ts), routed through the same SandboxAdapter a
sandboxed tool uses.
Time travel
Agent Forge keeps every run’s checkpoints, not just the latest: its file store (server/checkpointStore.ts) keeps the same bounded history as the
SDK’s LocalStorageCheckpointStore (the newest 50 saves per run, under
.lousho/agents/<id>/checkpoint-history/; see
Checkpoint history). From
that history you can fork a run at any step, change what happened there,
and replay it next to the original, with
AgentExecutor.fork() and
compareTrajectories() doing the work.
The History tab
- Run the agent (Topbar Run, or a chat message).
- Open the bottom drawer’s History tab. It lists the run’s steps: step number, status, the model’s finish reason, the tool calls made, and the tokens and cost of the step’s model call when known.
- Click Edit and replay from here on a step. Choose Append a user message and type one, or pick one of the step’s tool calls to edit its result (prefilled with the recorded result; text that parses as JSON is sent as JSON).
- Click Fork and replay. The run is forked at that step with your
edit and started as a new run,
<id>.fork-<n>. - The fork opens next to the original as a side-by-side trajectory: each model turn of both runs (text, tool calls and results), the first turn where they differ highlighted as diverged, and the drift entries (tool order, arguments, step count, finish reason) listed below. It refreshes when the fork finishes.
Routes
A run id is the run’s checkpoint session id: the agent id for the agent’s own runs,<id>.fork-<n> for a fork of run <id>. The runtime control
server has three routes for it (the History tab uses them), and two more for
an agent’s saved traces (the Trace tab uses them):
The flow, for an agent
weather that has run once:
Playground run endpoint
POST /playground/run runs a one-off prompt against a model and streams the
reply as server-sent events. It carries the same access token as the rest of
the API. The body:
messages(required): 1 to 200{ role, content },roleone ofsystem,user,assistant. They are sent as written; the server adds no system prompt of its own.variables: string values. Every{name}in every message’s content is replaced byvariables.name; a placeholder with no variable is left as is.model(required):provider/model, or a bare provider (mock). The provider key comes from Settings > Provider keys, then the environment, the same way agent runs resolve it.tools: tool names the Studio resolves for agents (current-date,day-name,http,web-fetch,demo-approval). A tool that needs approval ends the run withfinishReason: "awaiting-approval"; the playground has no approval flow.promptRef: the registry prompt the messages came from (name,name@labelorname@3). It is only recorded on the trace; the server does not fetch the prompt.
400 { error }. Otherwise the response is 200 with
content-type: text/event-stream, one data: <json> frame per event:
Every stream ends with exactly one
done or error, even a run that stops
without a result. usage has the run.done event’s usage shape
(AgentEventUsage).
Closing the connection aborts the run. Every run reports to the collector
the Studio reads (see The collector) as agent
playground, with lousho.prompt.ref on the run’s root span when
promptRef is given. A bearer token is sent when one is configured, for a
collector bound beyond loopback. A collector that is down does not slow or
fail the run.
Settings, secrets and deploy wiring
The Settings screen (#/settings, the last screen in the nav) and the builder
drawer’s Settings tab share three parts: provider API keys
(OpenAI and Anthropic, stored encrypted under ~/.lousho/studio/ and never shown
again; each key shows Set with its masked last characters, From
environment when only OPENAI_API_KEY / ANTHROPIC_API_KEY is set, or
Not set), named settings profiles (provider, deploy adapter, hook timeout,
OpenTelemetry toggle; kept in ~/.lousho/studio/settings.json, which holds no
secrets), and a Deploy section that picks an adapter (node-server,
docker or cloudflare-worker) and runs lousho build for the selected
agent. Other providers still read their environment variables, the same way
lousho dev/lousho build do (see Configuration), and
the mock provider needs no credentials.
Stored keys are encrypted with AES-256-GCM in ~/.lousho/studio/secrets.json.
The encryption key is generated on first use and kept next to it in
~/.lousho/studio/secrets.key (both 0600 on POSIX). This keeps keys out of
anything that copies the ciphertext alone - a backup, a zip of the project,
a shared agent YAML - but anyone who can read both files as your user can
decrypt them. It is not an OS keychain. Keep ~/.lousho/studio/ out of
version control and out of shared archives, and prefer environment variables
on shared machines.
An agent whose provider has no key (no stored key and no environment
variable) does not run. Run and Chat fail with
LOUSHO_PROVIDER_MISSING_API_KEY and a message naming the fix: add the key
in Settings, set the environment variable, or switch the agent’s provider to
mock. The studio never swaps in the mock provider on its own. The top bar’s
provider pill shows the provider/model the agent actually runs on, and a
mock agent carries a MOCK badge.
Dev mode
Dev mode exists only for people contributing to Studio inside the SDK’s own monorepo - an installed Studio is always the production bundle (see Production vs. dev mode). From a checkout of this repository,lousho studio detects the Studio source and falls back to dev
mode automatically as long as apps/agent-forge/dist-server hasn’t been
built yet:
tsx) and a real Vite
dev server with hot-module reload for apps/agent-forge/src/**, as two
sibling processes. Open the printed http://localhost:5173/?token=... URL; Vite
is pinned to port 5173 and the API server accepts that origin. To build the production bundle used by everyone else
(and to verify what actually ships):
npm run build:studio also runs automatically as part of the root
prepublishOnly script, so a published npm publish can never ship a
stale or unbuilt studio.
E2E smoke test
apps/agent-forge/e2e/studio.spec.ts is a headless Playwright test that
drives the real, built lousho studio (the same dist-server/index.cjs
production server, not a dev-mode Vite server) through a browser: it
creates an agent from the “Support bot” template, retargets its tool node
at a server-local demo-approval tool (always needsApproval: true -
see server/buildAgent.ts’s doc comment for why this exists, since none
of the SDK’s spec-resolvable built-in tools require approval), sends it a
chat message that triggers the mock provider’s tool-call heuristic, waits
for the run to pause on the approval gate, approves it via the Test tab’s
inline approval card, and asserts the run completes. Run it with:
build:studio), then runs Playwright
against it: studio.spec.ts above plus the other specs in
apps/agent-forge/e2e/, among them revamp.spec.ts (the revamp’s
acceptance checks: a failed run’s error in two interactions, every route
surviving a reload with its filters) and a11y.spec.ts (an axe scan of
every route in routeTable.ts). The daemon screens run against a fake
daemon (e2e/observeStub.ts and e2e/fixtures/seedObserve.ts), so no
lousho observe is needed.
Docs screenshots
The screenshots in this doc come fromapps/agent-forge/e2e/docShots.spec.ts,
which is skipped unless LOUSHO_DOC_SHOTS is set. After npm run build:studio, regenerate them from the repo root with:
docs/images/studio-<screen>.png (1280x800, light theme) from the
same fake daemon. The images are not part of the npm package. The dark
examples (studio-{agents,traces,trace,monitoring}-dark.png) come from the
same command with the dark scheme:
docs/images the spec skips its x- review shots, and a dark run
writes only those four.
Two optional variables help review a restyle before and after:
LOUSHO_DOC_SHOTS_OUT=<dir> writes the PNGs to another directory (absolute,
or relative to where you run the command), and LOUSHO_DOC_SHOTS_SCHEME=dark
shoots the dark theme (light is the default; any other value fails the run).
With an output directory every shot is written under its own name, x-
review shots included.